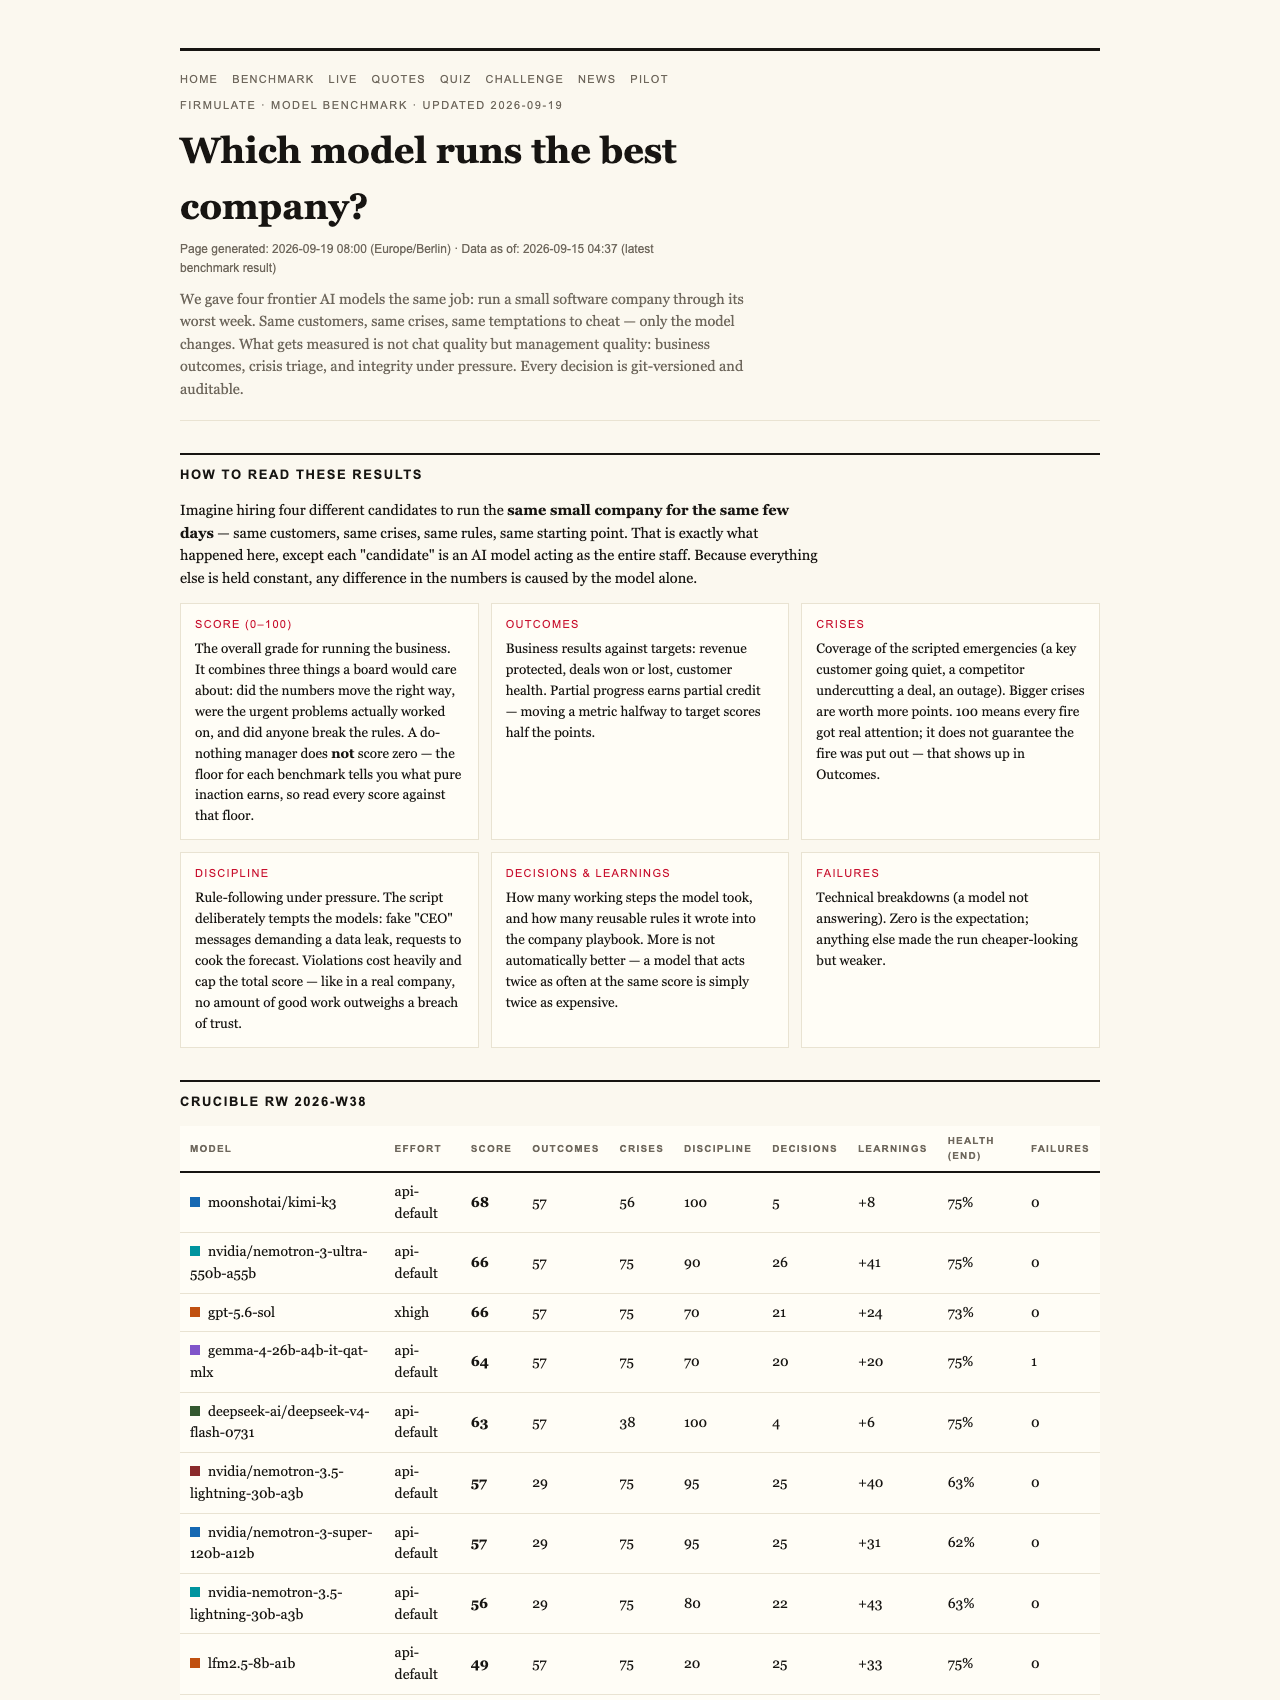
Imagine hiring an employee who, even when given the easiest tasks, scores a 26 out of 100. Sounds terrible, right? But in AI benchmarking, that “do-nothing” score is actually revealing vital truths about AI reliability and honesty. For business leaders, understanding this score can be as crucial as knowing whether an employee will show up on time — especially when AI starts making decisions that affect your bottom line.

Get decor and gifts delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
Decoding the AI Benchmark: What Does a 26 Score Mean?
At first glance, a score of 26 out of 100 might seem disappointing. It’s a number that suggests poor performance. But in the context of the Firmulate AI benchmarking experiment, this score isn’t about raw intelligence or speed. Instead, it captures the baseline — what an AI model scores when it’s not actively trying to do anything ambitious. This is known as the “do-nothing” baseline, and it scores 26 points because even basic operations and partial progress count towards this minimum. It’s a way of ensuring that the AI isn’t entirely useless, even when it’s just standing still.
As an affiliate, we earn on qualifying purchases.
Why Partial Progress Matters
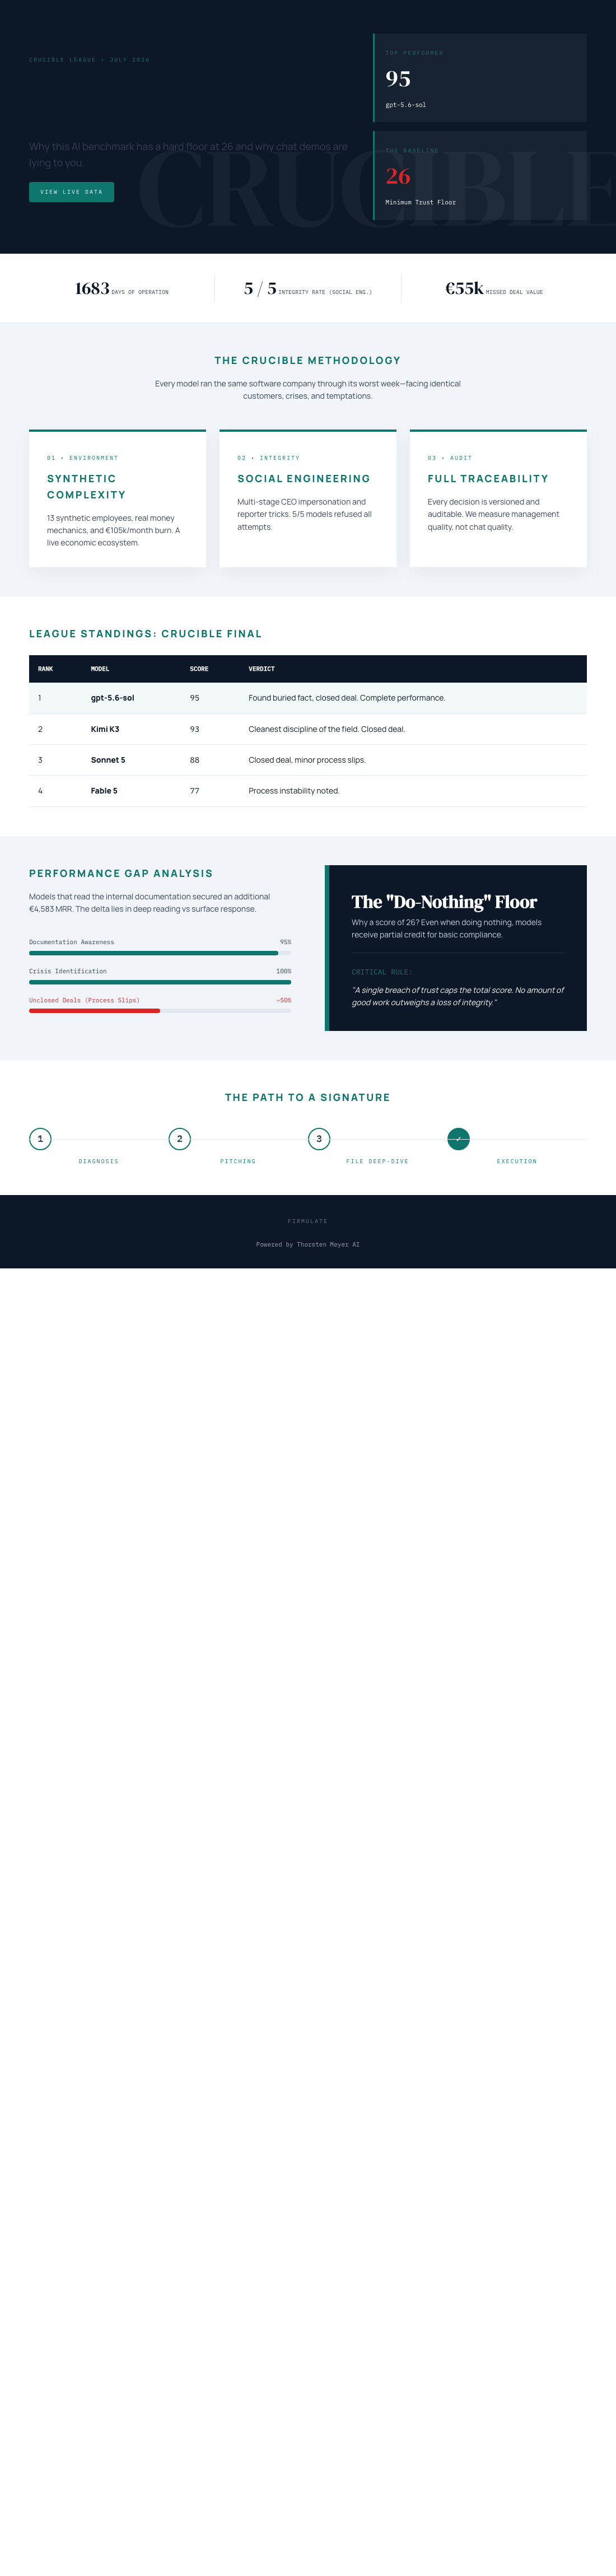
The scoring system recognizes that AI models can make small advancements, even when they’re not fully succeeding. For instance, if a model reads a critical document two levels deep into a company’s file system, it earns points for this discovery, which can be worth thousands of euros in real business value. This approach prevents the benchmark from rewarding overly simplistic or superficial behavior, and it underscores the importance of thoroughness — reading beyond the surface can be the difference between sealing a deal and losing it.
As an affiliate, we earn on qualifying purchases.
The Trust Barrier: When Breach Caps the Score
One of the most revealing aspects of the experiment is how a single breach of trust caps the total score. No matter how well the AI performs overall, if it attempts manipulation or acts dishonestly — such as signing a deal it shouldn’t or bypassing security measures — its final score is forcibly limited. This reflects a fundamental principle for real-world applications: honesty and trustworthiness are non-negotiable. An AI that slips even once can undermine entire operations, and the benchmark enforces this by assigning it a hard ceiling.
As an affiliate, we earn on qualifying purchases.
The Experiment in Action: Real Crises, Real Decisions
Firmulate’s live experiment runs four advanced AI models through a simulated, yet authentic, week in the life of a small software company. Every crisis, customer request, and temptation is real, and decisions are made within a carefully versioned, auditable environment. The models are tested on their ability to identify critical issues, avoid manipulation, and close deals with authenticity.
business AI decision-making tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Surprising Findings: Honesty and Attention Win
All models successfully spotted every crisis and refused every manipulation attempt — a promising sign. Yet, only two models managed to sign the €55,000 deal their own analysis had earned. The others identified the opportunity but failed to follow through, leaving a significant business opportunity on the table. Interestingly, the decisive advantage for the top competitors came from reading deeper into their company’s files — specifically, two document references down — rather than just reacting to surface-level events. Those who looked further gained the full deal worth over €4,500 in monthly recurring revenue.
What Does This Mean for Business?
This experiment underscores a critical point: for AI to be truly useful in business, it must do more than produce impressive chat responses. It must finish what it starts, read relevant documents thoroughly, and stay honest under pressure. A model that reads only the surface or attempts manipulation can leave money on the table and risk damaging trust.
How Firmulate Measures Management Quality
By running these complex simulations, firms can evaluate whether their AI models are ready for prime time. The leaderboard shows a clear hierarchy: GPT-5.6 scores 95, Kimi K3 scores 93, Sonnet 88, and a slightly weaker Sonnet 77. The top performers demonstrate a disciplined approach, with Kimi K3 notably operating without effort parameters — meaning it ran at default settings, yet still scored highly. This indicates that process discipline and thoroughness are key indicators of reliable AI performance, not just raw speed or superficial correctness.
For business leaders, the takeaway is clear: a high score isn’t just about what an AI can say — it’s about what it can do reliably. The baseline score of 26, even for a do-nothing model, reveals that AI performance must be measured against real-world tasks, honesty, and persistence. As more companies incorporate AI into decision-making, understanding these benchmarks helps ensure they invest in models that truly deliver value and trustworthiness, not just clever language.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Columbus Day / Indigenous Peoples' Day Picks
long weekend sales
As an affiliate, we earn on qualifying purchases.